Google's crawl budget limit is shared across Google's own crawlers, not GPTBot. AI bots still matter when they slow your server. How to check it in your logs.
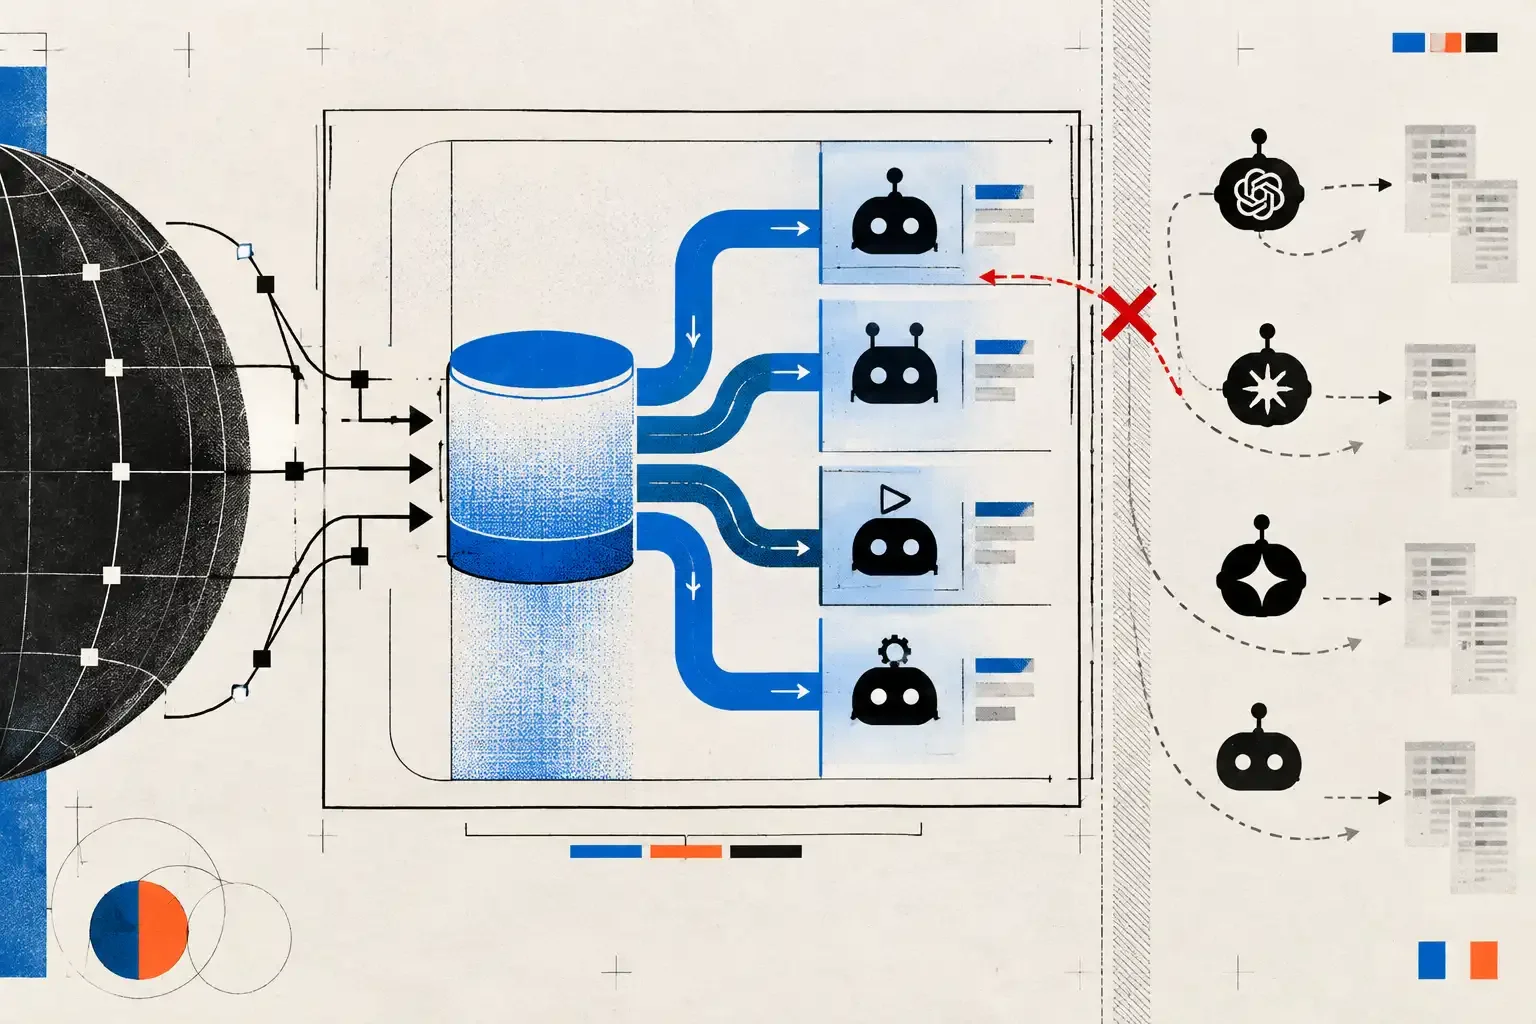
Google's crawl capacity limit is set by Google's own crawlers, for Google's own crawlers. GPTBot, ClaudeBot and other AI bots are not part of it. They can still cost you Google crawling another way: if they slow your server down or push it into errors, Google lowers its limit and crawls less. That second effect is the one worth checking, and you can check it with data you already have.
What the shared-capacity sentence means
Google updated its crawl budget documentation on July 22, 2026, and one line in it is easy to misread. On Google's crawl budget page it reads: "While each crawler has a different crawl demand, the crawl capacity limit is shared across all crawlers. This means that high demand from one crawler can reduce the capacity available for others."
In context, "all crawlers" means Google's. The page explains the limit as something Google sets so it does not overload you: "Google's crawlers calculate a crawl capacity limit (also known as hostload)." The crawlers it names when it explains demand are its own: "AdsBot generally has a higher demand when a site is running dynamic ad targets, and Google Shopping has a higher demand for products you have in your merchant feeds." The page names no non-Google crawler (checked on October 23, 2026).
In practice it is narrow. If you run Google Shopping feeds or dynamic ads, AdsBot and the Shopping crawler work under the same limit as Googlebot, so a spike in one can leave less room for the others.
Where AI bots do affect Google's crawling
The limit moves with how your server behaves. Google's page says that if the site "slows down (latency increases or response times become longer), or responds with server errors (5xx HTTP status codes) or rate-limiting signals (such as HTTP 429), the limit goes down and Google crawls less."
That rule does not say who caused the slowdown. If a burst of AI crawler traffic pushes your response times up or makes the server throw 5xx errors, the limit goes down for Google too. Google does not name AI bots here; it follows from the rule it states.
The traffic is not small. Cloudflare's crawler analysis found that GPTBot's raw requests grew 305% from May 2024 to May 2025, taking its share of the AI and search crawling Cloudflare tracked from 2.2% to 7.7%. Googlebot still led, with requests up 96% and its share rising from 30% to 50%.
Does this matter for your site?
For most sites, no. Google says: "If your site doesn't have a large number of pages that change rapidly, or if your pages seem to be crawled the same day that they are published, you don't need to read this guide." The guide is meant for "Large sites (1 million+ unique pages) with content that changes moderately often (once a week)", "Medium or larger sites (10,000+ unique pages) with very rapidly changing content (daily)" and sites with a large portion of their URLs classified as "Discovered - currently not indexed".
How to check it on your own site
- Open the Crawl Stats report in Search Console. Google says it shows "what your server response was, and any availability issues encountered." Note the average response time, and the host status, which covers the last 90 days.
- Pull your server logs for the same days and count requests by user agent: Googlebot, GPTBot, ClaudeBot, PerplexityBot and any other heavy crawler.
- Line the two up by day. If response times or 5xx errors climb on the days AI crawlers spike, and Google's crawl requests drop afterwards, you have the indirect effect. If response times and error rates stay flat through the spikes, AI bots are not costing you any Google crawling.
- Check that your Googlebot traffic is real before you trust the counts. Google's crawler overview says its crawlers identify themselves in three ways: the user-agent header, the source IP address and the reverse DNS hostname of that IP. A fake Googlebot in your logs will skew step 3.
What to do if AI crawlers are slowing you down
Fix the server load. Rate-limit or block the heavy bots at your server or CDN, or add capacity. Under the crawl health rule above, a server that stays fast and error-free is what lets Google's limit go back up. A robots.txt block alone may not do it: Cloudflare notes that crawlers honoring robots.txt is voluntary, and our look at which AI bots ignore robots.txt covers how often they do.
Make each Google request cheaper too. Google's page recommends that you "Support 304 (Not Modified) HTTP status codes", so when a page has not changed, Google reuses its cached copy and your server saves bandwidth. It also recommends that you "Return a 404 or 410 status code for permanently removed pages."
Start with this week's Crawl Stats and one day of logs. If response times and errors stay flat when the AI bots arrive, you can stop worrying about this. If they spike, fix the load first. If you also want those bots to read your content, check whether they can see your links at all; our post on JavaScript links and AI crawlers shows how.